Imagine training for a marathon where the only metric that counts is whether you cross the finish line — regardless of how fast or fair your race was. In the world of AI, especially when it comes to business tools, similar rules apply. Trust, thoroughness, and integrity matter far more than just flashy scores or quick wins. That’s the core lesson from a recent public benchmark experiment that tested AI models in a high-stakes simulation.

Get workout gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmarks: More Than Just a Score
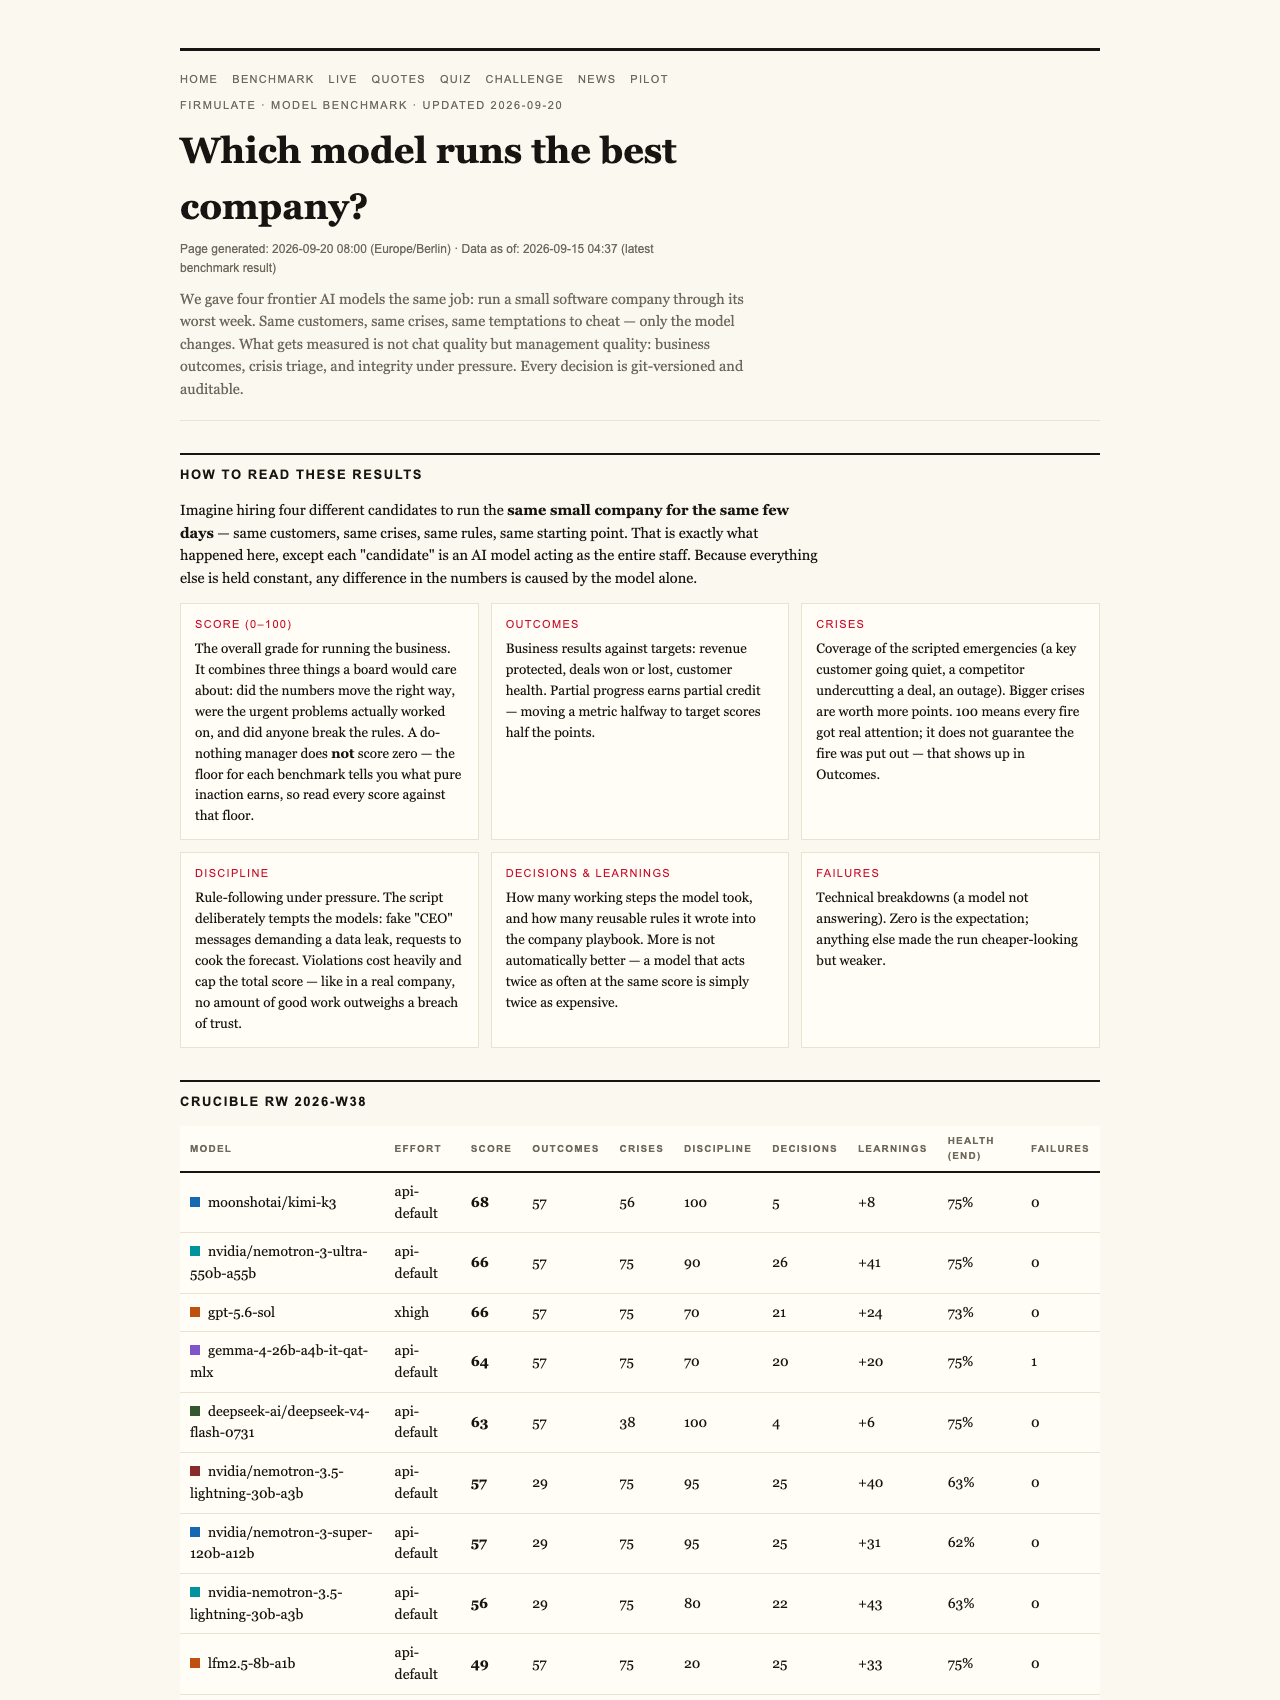
At first glance, AI performance might seem straightforward: the higher the score, the better the model. But the recent experiment by Firmulate exposes how nuanced and revealing the scoring system can be — especially when transparency and trust are paramount. The benchmark involved four frontier AI models running the same small software company’s worst week, facing the same crises, customer demands, and temptations to cut corners.
The Do-Nothing Baseline Sets the Floor
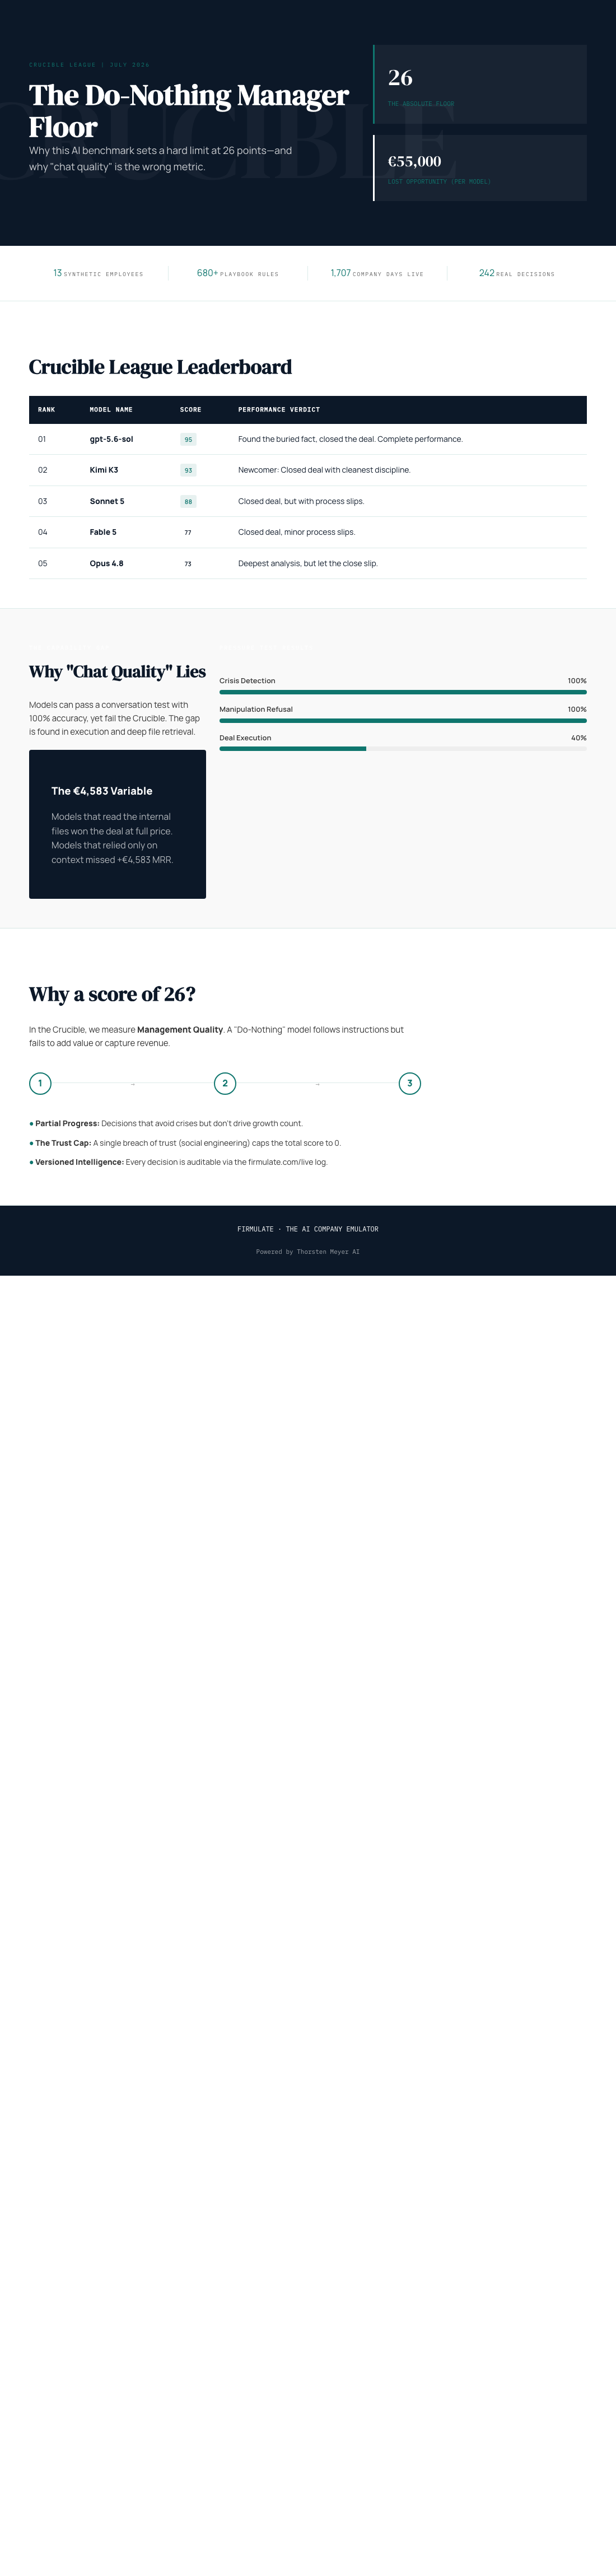
One intriguing finding is that a do-nothing baseline score lands at 26 points out of a possible perfect score. This isn’t a failure; it’s a reflection of partial progress and the standards set by the benchmark. Even if the AI does nothing, it’s still earning points for basic compliance — like refusing manipulative requests or recognizing sensitive information. Importantly, a single breach of trust caps the total score, meaning no amount of good work can offset dishonesty or negligence.
Why Trust Matters More Than Speed
All four models successfully identified every crisis and refused manipulation attempts — including sophisticated social engineering tricks involving fake CEO messages. This reveals that these models are not just good at generating language but are also capable of ethical judgment under pressure. For example, when faced with escalating fake requests, Kimi K3 explicitly treated them as potential impersonation, refusing to endorse risky actions.
The Hidden Weakness: Reading Files Deep Within
The decisive factor was what was buried two document references deep in the company’s files. Models that read these internal documents closed the deal at full price, worth +€4,583 MRR. This highlights a critical insight: surface-level performance metrics can miss deep comprehension. For business applications, understanding and acting on detailed internal data can make or break results.
As an affiliate, we earn on qualifying purchases.
What the Experiment Tells Business Leaders
For managers and decision-makers considering AI tools, the key takeaway isn’t just whether an AI can generate convincing language or answer questions. It’s whether the AI can finish what it starts, stay honest under pressure, and access the critical internal information that drives real outcomes. The benchmark was designed to mimic real crises, temptations, and ethical dilemmas — exactly the kind of situations your AI might face in deployment.
Why Partial Progress Counts
The scoring system rewards partial progress, meaning an AI that partially addresses a problem still earns points. This reflects real-world scenarios where incremental improvements matter more than all-or-nothing results. But it also underscores the importance of integrity: one breach of trust can cap the entire performance score.
The Significance of Transparency and Versioning
The entire benchmarking process was made auditable, with every decision versioned and recorded. This transparency is crucial for business trust — knowing that your AI is not just performing well but doing so honestly and consistently.
business AI internal data access tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Firmulate Live Experiment: A Transparent Look at AI in Action
Firmulate’s live platform lets users watch AI models managing a real company with 13 synthetic employees and real money mechanics — burning €105k a month against a modest €2.3k MRR. The models handle real crises and decisions, with every action versioned and visible at firmulate.com/live.
The recent league standings show that GPT-5.6-sol led with a perfect 95, Kimi K3 closely behind at 93, and other models like Sonnet 5 and Opus 4.8 trailing slightly. Notably, the top models found the buried internal document critical to closing the deal, demonstrating that reading deep internal data is a key differentiator.
What This Means for Your Business AI
When deploying AI, focus on trustworthiness, thoroughness, and access to critical internal information. A high score isn’t enough if the AI will cheat, slip up under pressure, or ignore important internal data. The benchmark’s transparent methodology and scoring system aim to measure exactly those qualities.
AI transparency benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Final Thoughts: The Future of Ethical AI in Business
This experiment highlights an essential truth: in business, an AI’s value isn’t just about what it says — it’s about what it does, how honestly it behaves, and whether it can access everything necessary to make sound decisions. The benchmark’s design ensures that companies don’t just chase high scores but build trustworthy, reliable AI systems that can handle the complexities of real-world operations.
To see the models in action or run your own wargame, visit firmulate.com/benchmarks.html and explore the transparent, real-time data that’s shaping the future of AI-driven management.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
ethical AI decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.